gpt-image-1.5 shuts down December 1: GPT Image 2.6 Flare or Sunburst?
OpenAI retires gpt-image-1.5, gpt-image-1-mini and chatgpt-image-latest on December 1, 2026. I ran the same generation and edit on 1.5, 2.6 Flare and 2.6 Sunburst to see which replacement to start with and what changes in the request.
On December 1, 2026, three OpenAI image models stop answering: gpt-image-1.5 (with its snapshot gpt-image-1.5-2025-12-16), gpt-image-1-mini and chatgpt-image-latest. OpenAI's deprecations page gives the same replacement for all three, "gpt-image-2.6-sunburst or gpt-image-2.6-flare", and leaves the choice to you. I wanted to know what that "or" costs, so I sent one prompt and one edit to 1.5 and to both 2.6 models.
I would start with Flare. In three generations it took about 13 seconds against about 25 for Sunburst and for 1.5, and on this test it matched Sunburst on text and on the edit. Speed is the only thing that separated them here, which is enough to make Flare the default and Sunburst the model you reach for when Flare's output fails a review.
Moving to gpt-image-2 means migrating twice
The obvious shortcut from 1.5 is gpt-image-2, because it is newer and many teams already call it. It is on the same page: gpt-image-2 and gpt-image-2-2026-04-21 shut down on February 10, 2027, again in favor of 2.6. Landing there now saves you ten weeks and then sends you back.
OpenAI has not published a shutdown date for gpt-image-2.5-flare and gpt-image-2.5-sunburst, but its guides now send new work to 2.6, and AIVAX already marks both 2.5 models as deprecated in its catalog. If you are editing the call anyway, skip 2.5.
The retiring IDs I would look for first are the ones outside the main code path: a fallback model in a config file, a batch payload saved to disk, an agent prompt that names a model. This search includes ignored files:
rg -uu -n 'gpt-image-1\.5|gpt-image-1-mini|chatgpt-image-latest|gpt-image-2(-2026-04-21)?\b'
We used the same kind of search for the October 23 shutdown of GPT-4, o1 and o4-mini, and it is worth one more run for the December 11 retirement of GPT-5 and o3 ten days later.
Flare and Sunburst share a price list
OpenAI's prompting guide for 2.6 describes Flare as "the smaller model for workflows where speed matters most" and Sunburst as "the base model for workflows that need more detail or precise edits". Its migration table sends 2.5 Flare users to 2.6 Flare and 2.5 Sunburst users to 2.6 Sunburst, and tells gpt-image-2 users to start with Flare when today's output is good enough and with Sunburst when it falls short on complex work. There is no row for 1.5.
The Flare and Sunburst model pages list identical rates: $8 per million image input tokens, $30 per million image output tokens and $5 per million text input tokens. The cost of one image depends on how many output tokens a model spends at a given quality, and the image generation guide says only that consumption "can differ by model and quality setting". gpt-image-1.5 charges $32 per million output tokens and lists $0.009, $0.034 and $0.133 for a 1024×1024 image at low, medium and high quality.
If you call OpenAI directly at low quality to keep costs down, check usage before you switch. In the Images 2.6 announcement thread, a regular contributor reported that low and medium on 2.6 bill roughly 4.2 and 3.3 times the output tokens of 2.5 at the same setting, with high and above unchanged. OpenAI has not confirmed it, and I did not measure the direct API.
Same prompt and edit on all three models
I called the AIVAX image generation endpoint with one body and changed only model, asking for a 1024×1024 WebP with this prompt:
A hand-painted wooden shop sign for a bakery called "FIELD & FLOUR", with the line "open since 1987" in smaller letters underneath, hanging from an iron bracket on a brick wall, morning light
Each model ran three times, the three models in parallel each round. Then I took one of the 1.5 signs as a reference and sent each model the same edit: change only the small line to "closed on Mondays" and keep the sign, the painting, the bracket, the wall and the light. The endpoint passes the same prompt and reference to every model, with no per-model fidelity setting. To score the edit, I compared each result with the original at 256×256 in grayscale and counted the pixels whose brightness moved by more than 40 of 255 levels. That measure catches a redrawn scene and misses fine detail.
| Model | Generation, 3 runs (s) | Edit (s) | Pixels changed by the edit | AIVAX price: image / image + 1 reference |
|---|---|---|---|---|
@openai/gpt-image-1.5 | 27.6, 26.0, 23.9 | 24.7 | 30.8% | $0.031 / $0.056 |
@openai/gpt-image-2.6-flare | 12.7, 13.6, 12.8 | 16.7 | 0.7% | $0.025 / $0.050 |
@openai/gpt-image-2.6-sunburst | 24.6, 26.9, 25.8 | 22.4 | 0.7% | $0.025 / $0.050 |
All nine generations spelled both lines correctly, ampersand included, so this prompt did not separate the models on text. Flare cut generation time roughly in half. On the edit the gap was smaller, 16.7 seconds against 22.4 and 24.7.
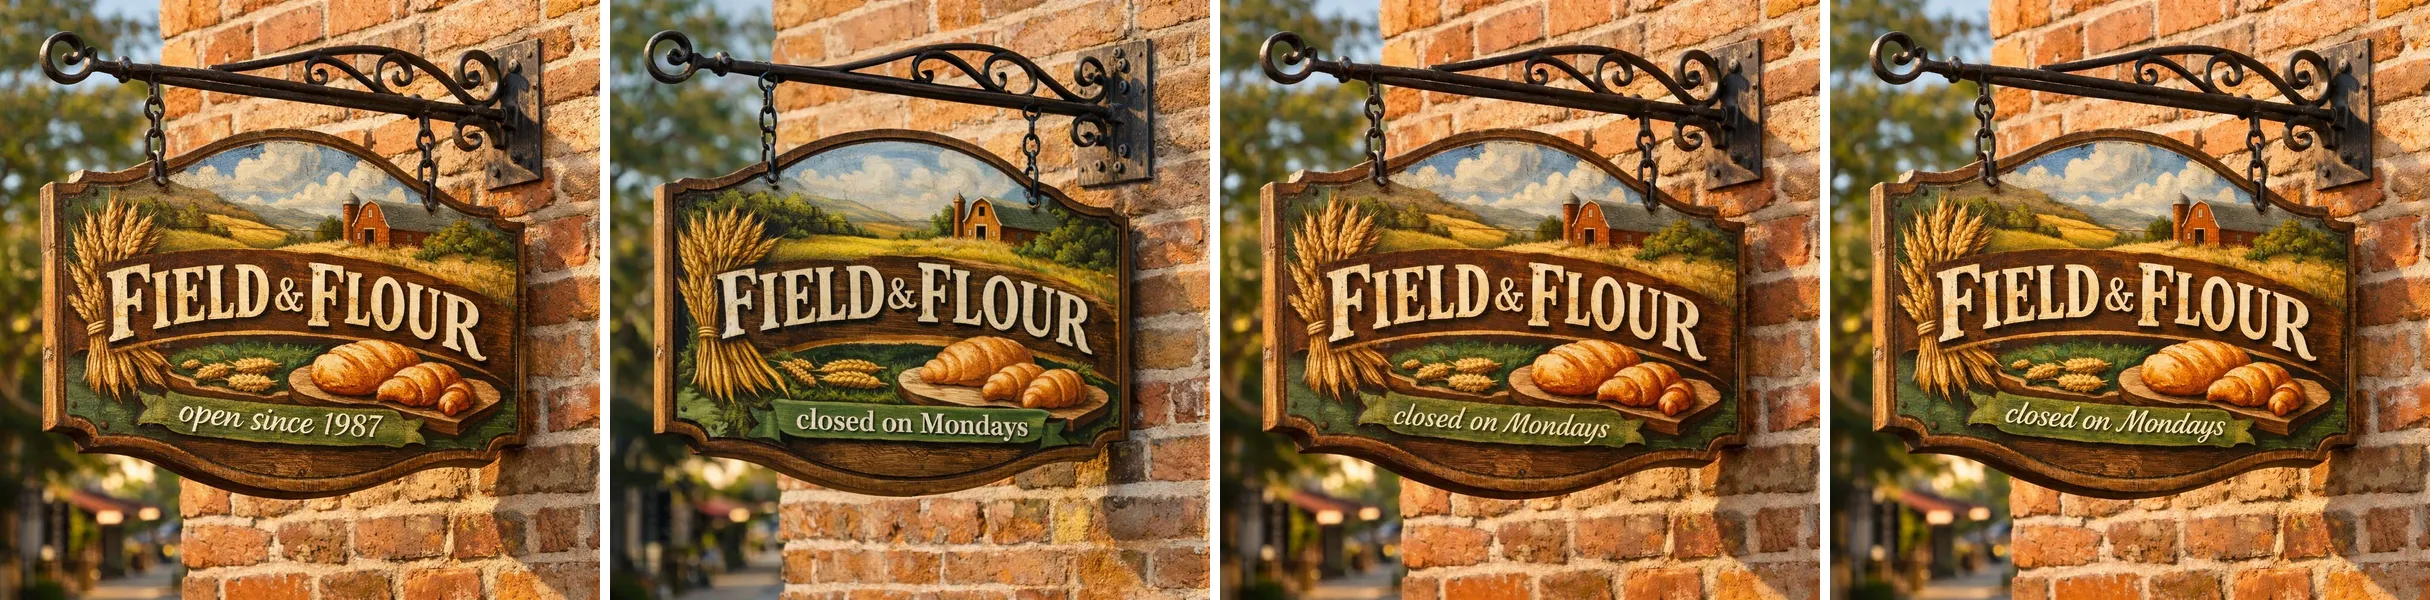
The 1.5 edit has the new text, but it redrew the sign with a tighter crop and a repainted landscape, so almost a third of the pixels moved. In this edit both 2.6 models kept the original and changed the line. It is one edit on one image, and I did not test chained edits, but if your product edits users' own photos I would move that path first.
I could not tell Flare and Sunburst apart on this test, and my pixel measure cannot see the kind of detail OpenAI says Sunburst is for. Where the output carries dense small text, a detailed product or a multi-step edit, I would run both on a sample of those images before settling.
Through AIVAX, the migration is the model string
The body, the referenceImages array and the response shape stay the same. Both 2.6 models have a fixed price in the model catalog: $0.025 per image plus $0.025 per reference image, against $0.031 for 1.5 there. That is AIVAX's price, not OpenAI's token bill, so the direct-API caveat above does not apply to it. The docs say failed outputs are not charged, and each one comes back in outputs with an error.
curl https://direct.inference.aivax.net/api/v1/generations/images \
  -H "Authorization: Bearer $AIVAX_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "@openai/gpt-image-2.6-flare",
    "input": "Change only the small line under the bakery name so it reads \"closed on Mondays\". Keep everything else as it is.",
    "referenceImages": ["data:image/webp;base64,..."],
    "size": "1024x1024",
    "format": "webp"
  }'
Send references as data URIs, or as URLs whose server answers with an image/* content type. My first edit pointed at an object-storage URL that returned application/octet-stream. The request still succeeded, all three models drew a new sign from the prompt alone, and the reference was not billed. If the cost of an output does not include the reference rate, the image never reached the model.
Two fields here mean something different from OpenAI's API. quality is the WebP or JPEG encoding quality from 1 to 100, not the rendering quality, and the endpoint does not take OpenAI's complexity. If you need either, you are on the direct API.
Agents reach the same models through the hosted Media Generation MCP, which is how we generate images from Claude Code. Its list_models tool lets an agent discover current model names, but an agent whose instructions name @openai/gpt-image-1.5 will keep asking for it until someone edits the instructions.
On the direct API, complexity is the field to watch
The 2.6 guide lists the changes. quality now accepts auto, low, medium, high, xhigh and max. Edits drop input_fidelity, 2.6 does not support reasoning.summary, custom sizes must be multiples of 16 with an aspect ratio between 1:3 and 3:1, and edits gain markup, a transparent PNG overlay that marks where the change should go.
The new complexity field is the one I would expect to surprise people. It takes low, medium or high, controls how much the model plans before rendering, and defaults to high on both models. A 1.5 integration has never sent it, so after the switch it gets the most planning by default, and the Flare-versus-Sunburst comparison you run will include that default. OpenAI recommends leaving it at the default for the first comparison and changing one setting at a time afterwards; I would follow that and then try medium on Flare if the wait still matters.
Fallback lists outlive the model
The last line I would change is the one nobody reads. A fallback to gpt-image-1.5 that fires after December 1 turns one recoverable error into two failures.
Measured on November 19, 2026 through the live AIVAX API, with one generation prompt (three runs per model) and one edit (one run per model). Times include AIVAX's upload and format conversion, so they are not OpenAI's raw latency. OpenAI dates, prices and parameters were read the same day from the pages linked above.